Benchmarks
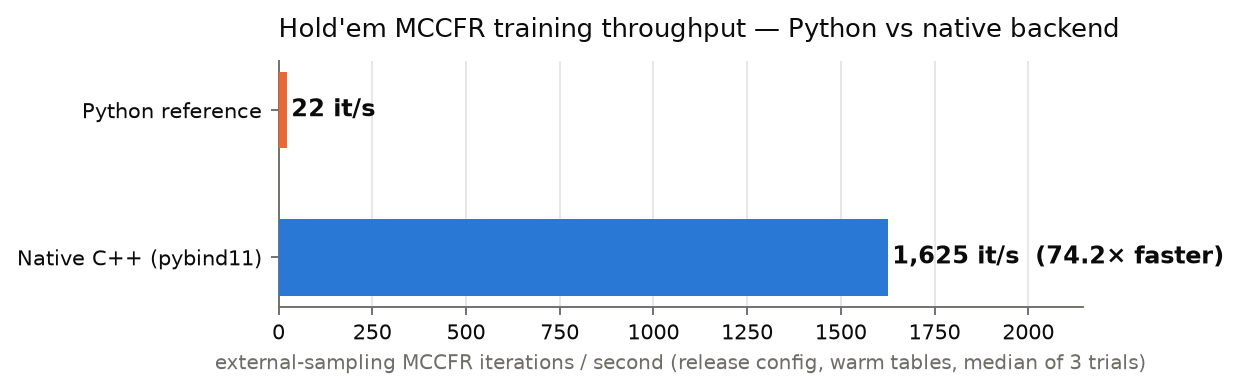
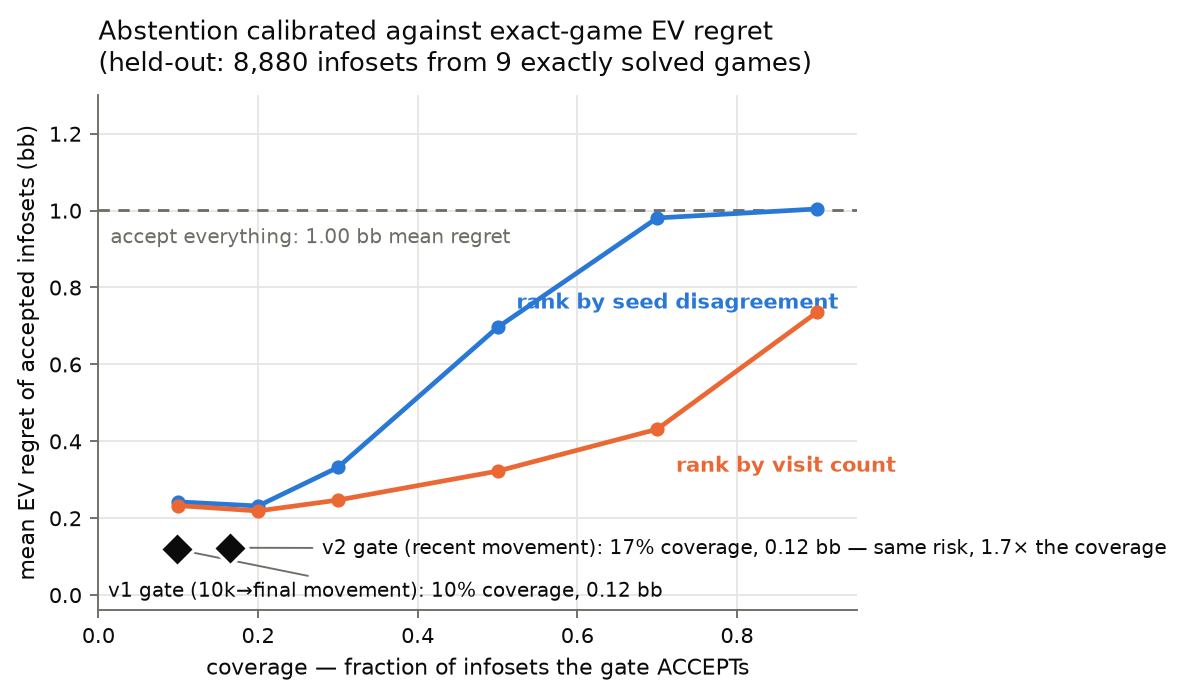
Committed, reproducible measurements — the figures below are generated by scripts in the repository from recorded results, not illustrations.
Local product performance
| API cold start → /health | ~1.6 s |
| Warm /analyze (2000 equity / 1000 rollout sims) | ~0.10 s |
| Full 169-hand preflop matrix (169 artifact lookups) | ~1.0 s |
Measured on an Apple-silicon laptop against the committed 2M release artifact; your numbers will vary with hardware and settings.
Reproduce everything: benchmark methodology · recorded results